
MatMulIntergerToFloat
Description
MatMulIntegerToFloat is used to perform a matrix multiplication (matmul) between integers (quantized) and convert the result to floating point (float).
Documentation illustration (illustration unavailable in the archive).
Input parameters
 specified_outputs_name : array, this parameter lets you manually assign custom names to the output tensors of a node.
 Graphs in : cluster, ONNX model architecture.
 A (heterogeneous) – T1 : object, N-dimensional matrix A.
B (heterogeneous) – T2 : object, N-dimensional matrix B.
a_scale (heterogeneous) – T3 : object, scale of quantized input ‘A’. It could be a scalar or a 1-D tensor, which means a per-tensor or per-column quantization. If it’s a 1-D tensor, its number of elements should be equal to the number of columns of input ‘A’.
b_scale (heterogeneous) – T3 : object, scale of quantized input ‘B’. It could be a scalar or a 1-D tensor, which means a per-tensor or per-column quantization. If it’s a 1-D tensor, its number of elements should be equal to the number of columns of input ‘B’.
a_zero_point (optional, heterogeneous) – T1 : object, zero point tensor for input ‘A’. It’s optional and default value is 0. It could be a scalar or a 1-D tensor, which means a per-tensor or per-column quantization. If it’s a 1-D tensor, its number of elements should be equal to the number of columns of input ‘A’.
b_zero_point (optional, heterogeneous) – T2 : object, zero point tensor for input ‘B’. It’s optional and default value is 0. It could be a scalar or a 1-D tensor, which means a per-tensor or per-column quantization. If it’s a 1-D tensor, its number of elements should be equal to the number of columns of input ‘B’.
bias (optional, heterogeneous) – T3 : object, 1D input tensor, whose dimension is same as B’s last dimension.
Documentation illustration (illustration unavailable in the archive).
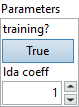
Parameters : cluster,
 training? : boolean, whether the layer is in training mode (can store data for backward).
Default value “True”.
 lda coeff : float, defines the coefficient by which the loss derivative will be multiplied before being sent to the previous layer (since during the backward run we go backwards).
Default value “1”.
 name (optional) : string, name of the node.
Output parameters
 Y (heterogeneous) – T3 : object, matrix multiply results from A * B.
Type Constraints
T1 in (tensor(int8), tensor(uint8)) : Constrain input A data type to 8-bit integer tensor.
T2 in (tensor(int8), tensor(uint8)) : Constrain input B data type to 8-bit integer tensor.
T3 in (tensor(float), tensor(float16)) : Constrain input a_scale, b_scale and output Y data type as float tensor.
Example
All these exemples are snippets PNG, you can drop these Snippet onto the block diagram and get the depicted code added to your VI (Do not forget to install Deep Learning library to run it).